Stop Paying for Search with These Open Source Semantic Search Gems
Why Open Source Semantic Search Is Worth Your Attention
Open source semantic search tools let you build powerful, meaning-based search into your apps and websites — without paying for proprietary platforms.
Here are the top open source semantic search tools to know:
| Tool | Best For | License |
|---|---|---|
| FAISS | Fast vector similarity search | MIT |
| Qdrant | AI-native vector database | Apache 2.0 |
| Milvus | Billion-scale search | Apache 2.0 |
| Chroma | LLM apps with memory | Apache 2.0 |
| Typesense | Developer-friendly hybrid search | GPL-3 |
| Meilisearch | Fast, plug-and-play search | SSPL |
| OpenSearch | Enterprise-grade semantic search | Apache 2.0 |
Traditional search matches keywords. It finds pages that contain your words — not pages that answer your question.
Semantic search is different. It understands meaning. It figures out what you’re actually asking, then finds the most relevant results — even if the exact words don’t match.
This matters because users don’t search like robots. They ask questions in natural language. They use synonyms. They expect smart results.
The good news? You don’t need a massive budget to build this. A rich ecosystem of open source tools now covers every part of the pipeline — from generating embeddings with models like Sentence Transformers, to storing and retrieving vectors at scale.
Whether you’re a developer building a product, or a business owner tired of clunky on-site search, these tools can help you deliver a much better experience.
The Core Components of an Open Source Semantic Search Pipeline
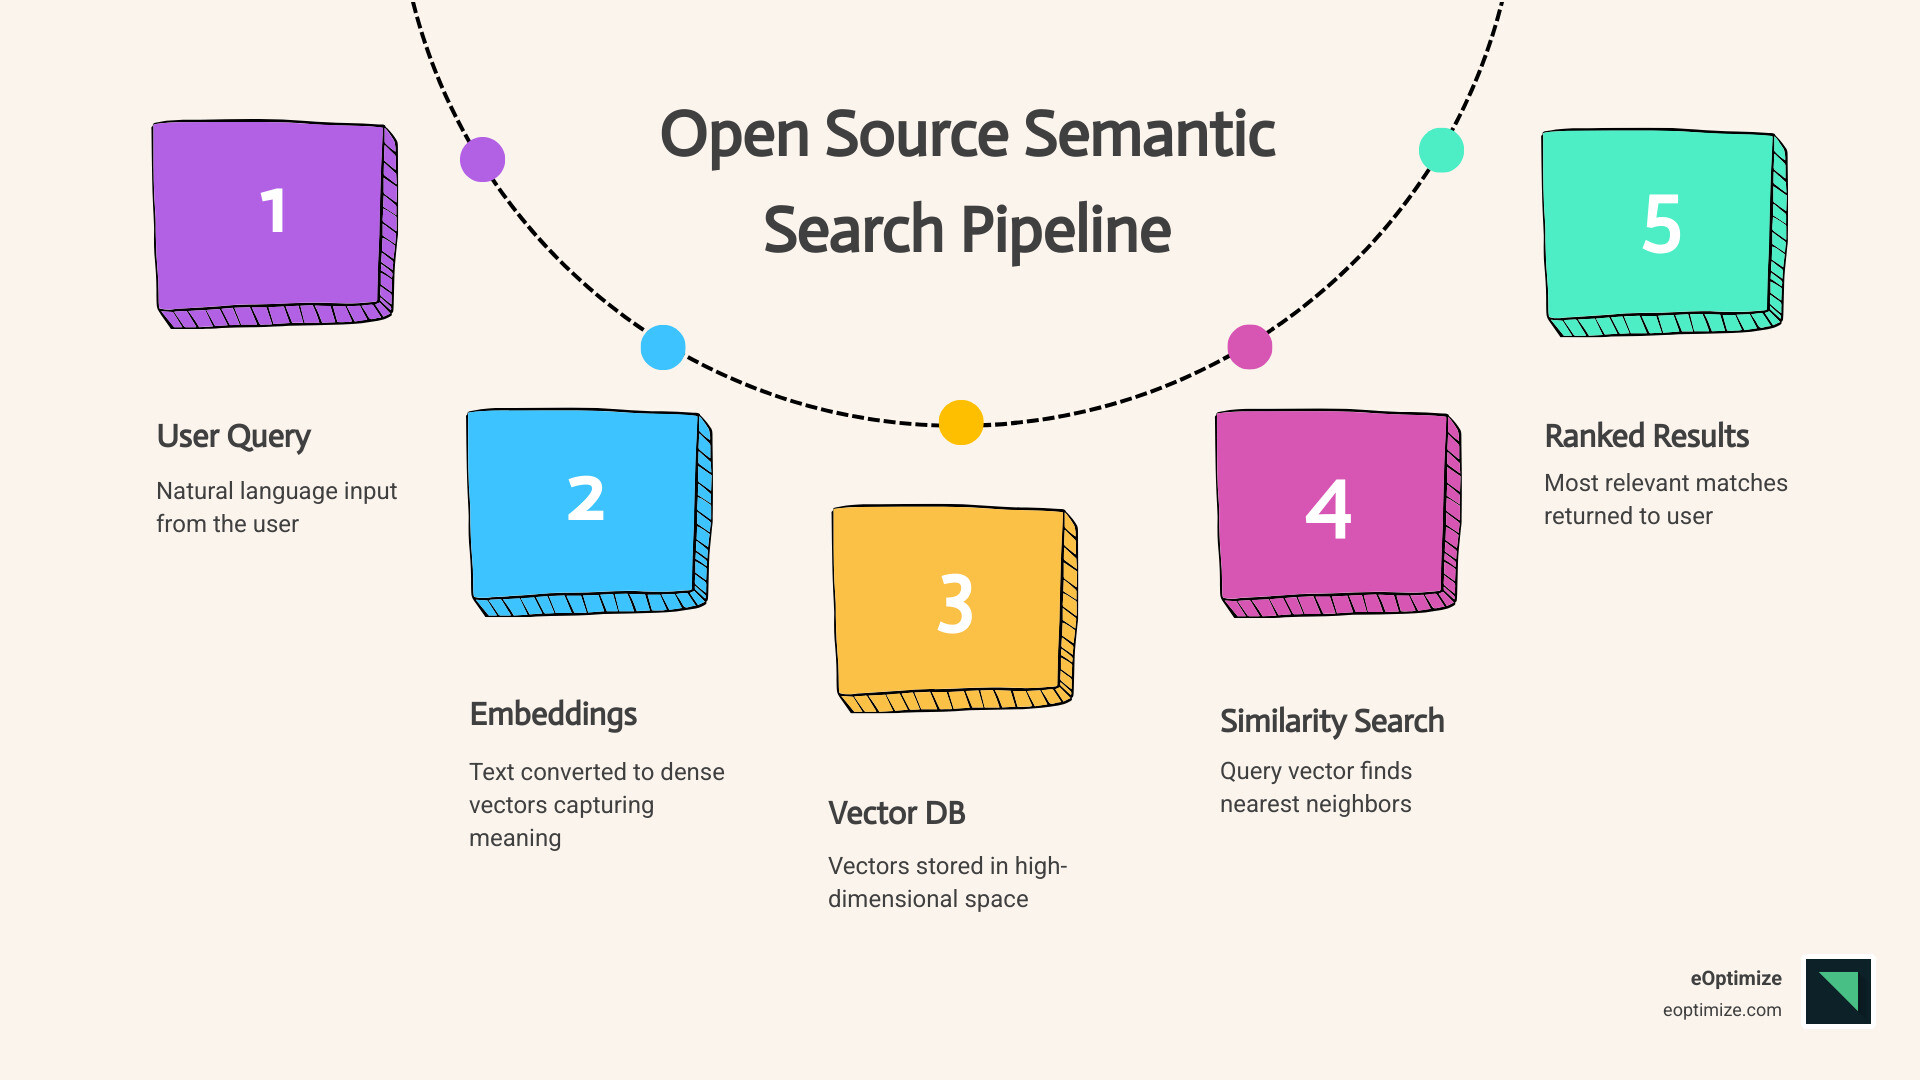
Building an open source semantic search system is like building a translation engine that converts human thoughts into mathematical coordinates. To get from a user’s typed query to a relevant result, your data must travel through a specific pipeline: embedding generation, vector storage, and similarity retrieval.
The journey begins with embedding generation. This is where raw text (or images and audio) is transformed into a “vector”—a long list of numbers that represents the essence of the content. If two sentences mean the same thing, their vectors will be numerically close to each other in a multi-dimensional space.
Once you have these numbers, you need a place to put them. This is vector storage. Unlike a traditional database that stores text in rows and columns, a vector database is optimized to store these numerical representations. Finally, similarity retrieval is the act of taking a new query, turning it into a vector, and asking the database: “Which of your stored vectors are closest to this one?”
Understanding this semantic search implementation is vital for anyone looking to move beyond simple word-matching. It allows for a search experience that feels intuitive rather than mechanical.
Generating Meaning with Open Source Semantic Search Models
The “brains” of the operation are the embedding models. These are often based on transformer architectures like BERT (Bidirectional Encoder Representations from Transformers). In open source, Hugging Face has become the go-to library for accessing thousands of pre-trained models that can generate these “dense vectors.”
When we talk about “latent space,” we are referring to the mathematical “room” where these vectors live. Imagine a giant 3D map where “Apple the fruit” is on one side near “Orange,” and “Apple the tech company” is on the other side near “Microsoft.” A good model knows the difference based on the context of the sentence.
For those new to the concept, it helps to Read the guide from OpenAI to understand how turning text into numbers makes it “understandable” to a machine. While OpenAI offers proprietary models, open-source alternatives like Sentence Transformers allow you to run these calculations on your own hardware, ensuring data privacy and reducing long-term costs.
Vector Databases vs. Traditional Keyword Search
Traditional search relies on “lexical matching.” It uses an inverted index—essentially a giant glossary—to find every document that contains the exact word “running.” If a user searches for “jogging,” a traditional system might fail unless the developer manually added “jogging” as a synonym.
In contrast, open source semantic search uses Approximate Nearest Neighbor (ANN) algorithms. One of the most popular is HNSW (Hierarchical Navigable Small World). Instead of checking every single document (which would be too slow), HNSW creates a “graph” that allows the search engine to skip through the data and find the closest matches in milliseconds.
This shift from matching characters to matching concepts is a cornerstone of modern discovery. By following an entity SEO best practices guide, developers can ensure their search systems recognize specific entities (like people, places, or brands) rather than just treating them as arbitrary strings of text.
Top Open Source Semantic Search Tools and Libraries
Choosing the right tool depends on your scale and technical comfort. Some tools are designed for massive, billion-vector datasets, while others focus on providing a “no-PhD-required” developer experience.
| Feature | FAISS | Milvus | Qdrant | Chroma |
|---|---|---|---|---|
| Primary Goal | Library for similarity | Enterprise Vector DB | AI-native Search | LLM App Memory |
| Language | C++ (with Python) | Go/Python/Java | Rust | Python/JS |
| Scalability | Single Node/GPU | Highly Distributed | Distributed | Single Node/Cloud |
| Best For | Research & Prototyping | Large Scale Production | High-Performance Apps | Fast AI Development |
If you are looking for a deeper dive into how these tools fit into a broader strategy, our semantic SEO guide explores the intersection of search technology and content visibility. For a direct starting point, check out Qdrant – Vector Database, which is specifically built for high-speed unstructured data retrieval.
High-Performance Engines: Milvus and Qdrant
When you need to search through millions or even billions of vectors, you need a heavy hitter. Milvus is a cloud-native vector database designed for massive scale. It supports GPU acceleration, which can significantly speed up the process of finding similarities in high-dimensional spaces. You can find its source code and community on the Milvus GitHub.
Qdrant, written in Rust, has gained a massive following for its balance of performance and ease of use. It isn’t just a database; it’s an AI-native search engine. It offers advanced features like “vector quantization,” which compresses vectors to save memory and increase search speed without sacrificing much accuracy.
Developer-Friendly Gems: Chroma and Typesense
Not every project needs a distributed cluster. Sometimes you just want to get a “Chat with your PDF” app running in ten minutes. Chroma is the fastest way to build LLM apps with memory. It is Apache 2.0 licensed and integrates seamlessly with Python and JavaScript. It handles the embedding generation for you by default using Sentence Transformers, making it a “plug-and-play” solution for many.
Typesense is another standout, often described as the “easier-to-use” alternative to complex enterprise engines. With 24K GitHub stars and 20M Docker pulls, it has a massive community. It’s designed to be “brick-shittingly good” at ranking and speed, often returning results in less than 50 milliseconds. For those working with an agency to implement these technologies, our semantic SEO agency ultimate guide provides a roadmap for integration.
Advanced Features in Open Source Semantic Search
The “holy grail” of search is Hybrid Search. This combines the best of both worlds: the conceptual understanding of vector search and the precision of keyword search (BM25). Sometimes, a user does want an exact match for a part number or a specific name, and pure semantic search might “hallucinate” a similar but incorrect result.
By integrating BM25 with vector retrieval, tools like Meilisearch and SemaDB provide a more robust experience. SemaDB is particularly interesting because it is a “no-fuss” multi-index engine that allows you to combine vector, keyword, and geo-search in a single query. You can learn more at SemaDB.
Implementing Hybrid Search for Maximum Relevance
To implement hybrid search, you typically use “sparse vectors” for keywords and “dense vectors” for meaning. A “reranking” step is often added at the end. In this step, a more powerful model (like a cross-encoder) looks at the top 10 or 20 results and re-orders them to ensure the absolute best answer is at the top.
This approach is crucial for semantic entity SEO for AI, as it ensures that the search engine respects the specific entities mentioned in a query while still understanding the underlying intent.
Local and Private Open Source Semantic Search
Privacy is a growing concern. Many organizations cannot send their sensitive data to cloud-based LLM providers. Fortunately, the open-source community has responded with “Offline RAG” (Retrieval-Augmented Generation) solutions.
One practical example is the Zotero RAG Assistant. It allows academics and researchers to semantically search their personal PDF libraries locally. By using local LLM runners like Ollama or LM Studio, you can have a fully functional semantic search assistant that never sends a single byte of data to the internet.
For a more general-purpose local solution, Open Semantic Search provides an integrated search server that includes OCR for images and crawling capabilities for local filesystems, all built on top of Apache Solr and Tika.
Deploying and Benchmarking Your Search Infrastructure
Deploying open source semantic search has become significantly easier thanks to containerization. Most of these tools offer official Docker images and Kubernetes Helm charts. This allows you to spin up a production-ready vector database with a single command.
However, once it’s running, you need to know how it performs. The two key metrics are Recall (how many of the truly relevant results were found) and QPS (Queries Per Second). There is usually a trade-off: higher accuracy often means slower searches.
Tools like ANN-Benchmarks provide a standardized way to compare these engines. For example, SemaDB has been shown to achieve 0.990 recall at over 500 QPS on standard datasets, which is impressive for a “no-fuss” engine.
Scaling Open Source Semantic Search in Production
As your data grows, you’ll need to look at sharding (splitting the database across multiple servers) and high availability (ensuring the search stays up if one server fails). Most enterprise-grade open-source tools use protocols like Raft to manage data consistency across a cluster.
Another vital feature for production is metadata filtering. You don’t just want the “most similar” document; you want the “most similar document from 2023 that is tagged as a ‘Report’.” Being able to filter by metadata while performing a vector search is what separates a toy project from a professional search engine. This level of entity SEO optimization is what allows users to find exactly what they need in a sea of data.
Frequently Asked Questions about Semantic Search
How does semantic search differ from traditional keyword search?
Traditional search looks for exact character matches (lexical search). If you search for “feline,” it won’t find “cat” unless you’ve manually linked them. Semantic search understands the relationship between words. It uses vector embeddings to find results based on the intent and context of the query, not just the letters used.
What is the best open-source vector database for small projects?
For small projects or those just starting with AI, Chroma and Typesense are excellent choices. They are easy to set up, have great documentation, and don’t require complex infrastructure. If you need something that runs as a simple library within your Python code, FAISS is the industry standard for prototyping.
Can I run semantic search entirely offline for privacy?
Yes! By combining an open-source vector database (like Qdrant or Chroma) with a local embedding model (via Sentence Transformers) and a local LLM (via Ollama), you can build a complete “Chat with your data” system that runs entirely on your own hardware without an internet connection.
Conclusion
The world of search is moving away from “blue links” and toward “answers.” By leveraging open source semantic search, you can build systems that understand your users, respect their privacy, and scale with your needs.
We are already seeing the next wave of technology: multi-modal search. This allows users to search for images using text, or find videos using audio clips, all within the same vector space. As these tools continue to evolve, the barrier to entry for building world-class search experiences will only get lower.
For those looking to stay ahead of these trends, our semantic SEO for AI ultimate guide offers deep insights into the future of information retrieval. The gems are out there—it’s time to start building.